AI-Powered Code Tooltips in Docusaurus — Explain Like I'm Five
Add hover tooltips to tricky code lines in your Docusaurus blog — powered by Claude, generated at build time, zero browser latency. Covers the remark plugin, the React renderer, and the CLI script.


This article is part of the Creating Docusaurus components series:
- Change how Docusaurus will create img tags
- Overrides the generation of img tags with Docusaurus
- Organize Your Docusaurus Content with a Custom Series Component
- Providing a go to the top button in Docusaurus posts
- Creating a search&replace plugin for Docusaurus
- A component for showing code snippets in a Docusaurus blog
- A Docusaurus component that alerts readers the article is over a year old
- Showing the changelog of your post
- Inject ASCII Art in any HTML pages rendered by Docusaurus
- Best Practice - Customizing the Docusaurus RSS Feed for Full Content & Images
- Running some checks on your Docusaurus images
- Tags management in Docusaurus
- Automating TL;DR Summaries with Gemini AI
- Introducing the ProjectSetup Component - A Standardized Way to Share Project Structures
- How to indicate AI-assisted content in a Docusaurus blog
- Bring Your CLI Tutorials to Life with a Typewriter Terminal
- Meerkat Mischief: Sprinkling Easter Eggs Across my Blog
- AI-Powered Code Tooltips in Docusaurus — Explain Like I'm Five
- Adding Reader Reactions to Your Docusaurus Blog
- Your Blog Is Unreadable to an AI. Here Is the Fix.
- Shake Your Phone, Startle the Meerkat
- Add a "Copy as Markdown" Button to Your Docusaurus Blog
- Ask My Blog: Turning 259 Articles Into 2,160 Searchable Questions
- The Third Door: A Floating Chat Bubble, and the Feature Nobody Could Find
- Drawing a Map of My Own Blog
- Let Readers Flag Issues — A Multi-Type Feedback Widget for Docusaurus
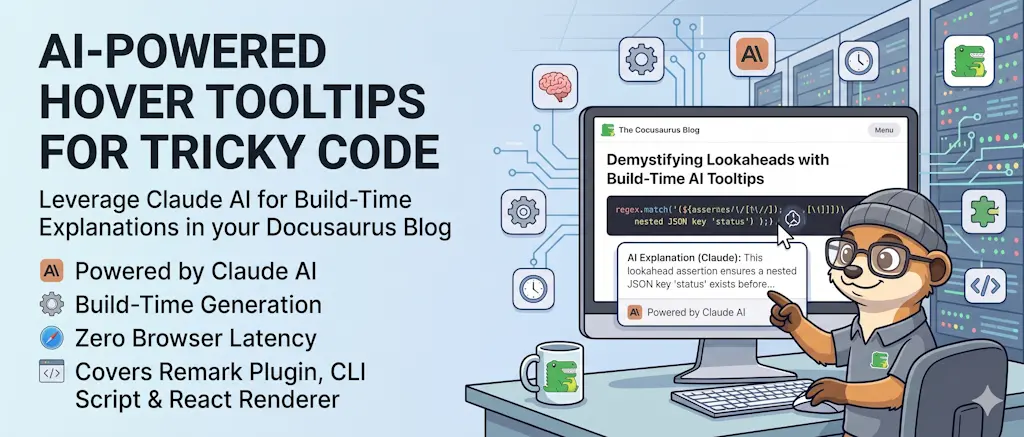
Your Dockerfile is crystal-clear to you. To a junior reader, RUN npm ci --omit=dev is gibberish. This article adds a ? badge to the tricky lines of your <Snippet> code blocks. Hovering reveals a plain-English explanation generated once by Claude and stored in a JSON file — no API key in the browser, no hover latency. The whole system has three parts: a Node.js script that calls the Claude API and writes a .eli5.json file, a one-line extension to your existing remark-snippet-loader plugin that auto-injects the annotations, and a custom React renderer inside the Snippet component that overlays the badges. The author workflow is: run the script, commit the JSON, done.
When you write a tutorial aimed at developers who are learning, there is always a gap between what you assume they know and what they actually know. You could add inline explanations — but that bloats the article. You could add a glossary — but readers skip it. What you really want is optional, on-demand context that appears exactly where the reader is confused.
That is what this feature does. A small ? badge floats at the right edge of annotated lines. Hover it, and a tooltip explains the line in simple English. Move away, and the code is clean again.
What it looks like
  ┌─ Dockerfile ─────────────────────────────────────────── ▾ ─┐
  │  1  FROM node:20-alpine                               [?]  │
  │  2                                                         │
  │  3  WORKDIR /app                                           │
  │  4  COPY package*.json ./                             [?]  │
  │  5  RUN npm ci --omit=dev                             [?]  │
  │  6                                                         │
  │  7  COPY . .                                               │
  │  8  EXPOSE 3000                                       [?]  │
  │  9  CMD ["node", "server.js"]                         [?]  │
  └────────────────────────────────────────────────────────────┘
             ↓ hover [?] on line 5
  ┌──────────────────────────────────────────────────────────────┐
  │  npm ci installs exactly what's in package-lock.json.        │
  │  --omit=dev skips dev tools — keeps your image smaller.      │
  └──────────────────────────────────────────────────────────────┘
The ? badges appear only on lines that Claude decided are non-trivial. Blank lines, closing braces, and self-evident assignments are skipped automatically.
The same idea works in the terminal: ai-explain pipes a script or an error message to a local Ollama model and prints a plain-English explanation.
Architecture
The system has three moving parts that work independently:
  ① scripts/generate-eli5.mjs          (run once, by the author)
        ↓  calls Claude API
        ↓  writes blog/2026-xx-xx-my-post/files/Dockerfile.eli5.json
        ↓  commit that file

  ② plugins/remark-snippet-loader       (runs at build time, automatically)
        ↓  reads Dockerfile
        ↓  finds Dockerfile.eli5.json alongside it
        ↓  injects eli5json="..." prop into <Snippet>

  ③ src/components/Snippet/index.tsx   (runs in the browser)
        ↓  parses eli5json prop
        ↓  renders Prism-highlighted code line by line
        ↓  overlays ? badges with tooltips
The key design decision is that AI calls happen at authoring time, not at read time — the very same pattern I used to generate my TL;DR summaries with Gemini. The .eli5.json files are committed to git and bundled with the site like any other static asset. Readers never wait for an API call, and your API key never leaves your machine.
Step 1 — The annotation script
Create scripts/generate-eli5.mjs. This script reads a source file, sends it to Claude with a prompt that asks for line-by-line explanations, and writes the result as a JSON file alongside the source.
#!/usr/bin/env node/** * Generate "Explain Like I'm Five" annotations for a source file. * * Usage: * node scripts/generate-eli5.mjs <source-file> [--force] [--output <path>] [--locale <code>] * node scripts/generate-eli5.mjs --locale fr --articles <article-path>... [--dry-run] * * Reads ANTHROPIC_API_KEY from process.env or a .env file at the project root — unless * --backend ollama is passed, which calls the local model instead and needs no key. * Writes <source-file>.eli5.json alongside the source file (or to --output path). * * With --locale (TODO 0121), the output language changes but THE INPUT DOES NOT: an ELI5 * describes code, and the code is identical in every locale. There is no "generate from the * translated article" here — that is the shape of the sibling question index (TODO 0120), * which describes prose. The localized sidecar is written next to the code it explains, as * `<source>.eli5.<locale>.json`, because `files/` is never duplicated under `i18n/` * (plugins/remark-i18n-assets). * * --articles is the batch `translate` calls once an article is translated: it asks * `scripts/lib/i18n-eligibility.mjs` which of that article's snippets are eligible, and never * re-derives the three conditions itself. With --dry-run it constructs no client and spends * nothing, which is what makes the cost quotable before the confirmation prompt. */
import fs from "fs";import path from "path";import { fileURLToPath } from "url";import { createRequire } from "module";import { hashSource } from "./lib/eli5-hash.mjs";import { cmd } from "./lib/cheatsheet-hint.mjs";import { DEFAULT_BACKEND, ELI5_BACKENDS, callEli5Backend, modelFor, printCostNotice, resolveBackend,} from "./lib/eli5-backend.mjs";import { ELI5_COST_PER_FILE, articleKeyOf, eli5Candidates,} from "./lib/i18n-eligibility.mjs";
const require = createRequire(import.meta.url);const __dirname = path.dirname(fileURLToPath(import.meta.url));const projectRoot = path.resolve(__dirname, "..");
// Load .env from project root (best-effort)try { const dotenv = require("dotenv"); // quiet: dotenv's banner goes to stdout, which would corrupt the single "<count>\t<cost>" // line that --porcelain promises to the shell. dotenv.config({ path: path.join(projectRoot, ".env"), quiet: true });} catch { // dotenv not available — rely on environment variables already set}
/** * Escapes the backslashes that do not start a valid JSON escape sequence. * * A snippet whose CODE contains a regex makes the model quote that regex back inside its * explanation, and `~* \.(?:css|js)$` carries a `\.` — a perfectly good regex, an invalid JSON * escape, "Bad escaped character in JSON". It cost the nginx.conf annotation of * `running-docusaurus-with-docker` two full runs before the cause was clear, because the * fenced-response fallback looks like it should already have handled a malformed answer. * * Safe to run over the whole document: in JSON a backslash may only ever appear inside a string, * so any backslash that is not part of `\" \\ \/ \b \f \n \r \t \uXXXX` is a literal the model * failed to escape. Valid escapes are matched first and handed back untouched, `\u` included — * doubling those would corrupt the text this is meant to save. */function repairLoneBackslashes(text) { return text.replace(/\\(u[0-9a-fA-F]{4}|["\\/bfnrt])|\\/g, (whole, valid) => valid ? whole : "\\\\", );}
// Language detection — mirrors the mapping in remark-snippet-loaderconst EXT_TO_LANG = { js: "javascript", mjs: "javascript", cjs: "javascript", jsx: "jsx", ts: "typescript", tsx: "typescript", py: "python", php: "php", sh: "bash", bash: "bash", zsh: "bash", css: "css", html: "html", json: "json", yml: "yaml", yaml: "yaml", md: "markdown", mdx: "markdown", dockerfile: "docker", ini: "ini", sql: "sql", xml: "xml", toml: "toml", env: "bash", txt: "plaintext", ps1: "powershell", bat: "batch", cmd: "batch",};
const BASE_NAME_TO_LANG = { dockerfile: "docker", ".env": "bash", ".gitignore": "plaintext", ".dockerignore": "plaintext", makefile: "makefile",};
function detectLang(filePath) { const baseName = path.basename(filePath).toLowerCase(); if (BASE_NAME_TO_LANG[baseName]) return BASE_NAME_TO_LANG[baseName]; const ext = path.extname(filePath).slice(1).toLowerCase(); return EXT_TO_LANG[ext] || ext || "plaintext";}
// Output language per locale. `en` carries no extra instruction — it is what the prompt below// already asks for, and 798 existing sidecars were generated without one.const LANGUAGES = { en: { name: "English", extra: "" }, fr: { name: "French", extra: `
Write the "summary" and every value in "explanations" in FRENCH. Keep codeidentifiers, file names, commands, flags and option names exactly as they appearin the source — translate the prose around them, never the code itself. Use thevouvoiement-free, direct technical register of French developer documentation.`, },};
const systemPromptFor = ( locale,) => `You are a patient senior developer explaining code to a junior colleague.Given a source file with numbered lines, produce two things:
1. "summary": two to four plain sentences narrating what this snippet does as a whole and why, the way you'd explain it out loud to someone reading over your shoulder — not a recap of individual lines. No jargon unless immediately defined.2. "explanations": for each line a junior developer might find confusing, one or two plain sentences. Think "explain like I'm five but I'm also a developer". Skip blank lines, closing braces/brackets, import lines that are self-evident, comments that already explain themselves, trivially obvious assignments.
Return ONLY a valid JSON object shaped exactly like:{"summary": "...", "explanations": {"3": "...", "7": "..."}}Keys in "explanations" are line numbers as strings. Omit lines that need noexplanation. No markdown, no code fences.${LANGUAGES[locale].extra}`;
/** Where a locale's sidecar lives. `en` keeps the historical unsuffixed name. */function sidecarPath(absSource, locale) { return locale === "en" ? `${absSource}.eli5.json` : `${absSource}.eli5.${locale}.json`;}
async function generateEli5( sourceFile, { force = false, outputPath = null, locale = "en", backend = DEFAULT_BACKEND, quoteCost = true, } = {},) { if (!LANGUAGES[locale]) { throw new Error( `Unsupported locale "${locale}" (known: ${Object.keys(LANGUAGES).join(", ")}).`, ); }
const absSource = path.resolve(sourceFile);
if (!fs.existsSync(absSource)) { throw new Error(`Source file not found: ${absSource}`); }
if (fs.statSync(absSource).isDirectory()) { throw new Error( `"${sourceFile}" is a directory.\n` + ` To process an entire directory, use the bulk script instead:\n` + ` ${cmd("eli5:bulk", "--dir", sourceFile)}`, ); }
const destPath = outputPath || sidecarPath(absSource, locale);
if (!force && fs.existsSync(destPath)) { console.log(`⏭ Skipped (already exists): ${path.relative(projectRoot, destPath)}`); console.log(` Use --force to regenerate.`); return { skipped: true }; }
const code = fs.readFileSync(absSource, "utf-8"); const lang = detectLang(absSource); const lines = code.split("\n");
// Number the lines for the prompt const numberedCode = lines.map((line, i) => `${i + 1}: ${line}`).join("\n");
const maxTokens = lines.length > 50 ? 2048 : 1024; const model = modelFor(backend);
// `quoteCost`: the batch modes below announce the whole run's price once, before the first // call — repeating "1 file × $0.01" on every iteration would bury it. if (quoteCost) printCostNotice(backend, 1);
console.log( `🤖 Calling ${model} for ${path.basename(absSource)} (${lines.length} lines, lang: ${lang}` + `${locale === "en" ? "" : `, text: ${locale}`})...`, );
const raw = await callEli5Backend({ backend, systemPrompt: systemPromptFor(locale), userContent: `Language: ${lang}\n\n${numberedCode}`, maxTokens, });
// Parse JSON — strip markdown fences if the model wrapped it anyway, then repair the one // malformation it produces on its own (see repairLoneBackslashes). Both backends go through // this: a grammar-constrained local answer is not trusted any more than a paid one. const candidates = [raw]; const fenced = raw.match(/\{[\s\S]*\}/); if (fenced) candidates.push(fenced[0]); candidates.push(...candidates.map(repairLoneBackslashes));
let parsed; for (const candidate of candidates) { try { parsed = JSON.parse(candidate); break; } catch { // Try the next shape; the throw below reports the original text, never the repaired one. } }
if (!parsed) { throw new Error(`Could not parse the ${model} response as JSON:\n${raw}`); }
const summary = typeof parsed.summary === "string" && parsed.summary.trim() ? parsed.summary.trim() : null;
// Validate: only keep string values with string-number keys const explanations = parsed.explanations && typeof parsed.explanations === "object" ? parsed.explanations : {}; const cleaned = {}; for (const [k, v] of Object.entries(explanations)) { if (/^\d+$/.test(k) && typeof v === "string" && v.trim()) { const lineIdx = parseInt(k, 10) - 1; if (lineIdx >= 0 && lineIdx < lines.length) { cleaned[k] = v.trim(); } } }
const result = { version: 1, // The model that actually wrote this file — not a constant. Reading a sidecar is how you // tell an Haiku annotation from one produced locally while iterating on the prompt. model, generated: new Date().toISOString(), source: path.basename(absSource), sourceHash: hashSource(code), lang, // `lang` is the language of the CODE (yaml, bash); `textLang` the language of the prose. // Reusing one key for both senses is the contresens TODO 0121 called out up front. textLang: locale, summary, explanations: cleaned, };
fs.writeFileSync(destPath, JSON.stringify(result, null, 2) + "\n"); console.log( `✅ Written: ${path.relative(projectRoot, destPath)}\n ${Object.keys(cleaned).length} annotations on ${lines.length} lines, summary: ${summary ? "yes" : "no"}.`, );
return { skipped: false, destPath, count: Object.keys(cleaned).length };}
/** * Generate the localized sidecars of one or more ARTICLES' snippets. * * What is eligible is decided entirely by `scripts/lib/i18n-eligibility.mjs` — article really * translated, English sidecar present, localized one missing or stale. Nothing here re-tests * any of that, which is why `--force` has no meaning in this mode: a file the module returned * is one that needs writing, and a file it withheld must not be paid for again. That is what * makes `translate <path> --force` free of ELI5 charges when the code did not change. */async function runArticleBatch({ locale, articlePaths, dryRun, porcelain, assumeTranslated, backend = DEFAULT_BACKEND,}) { if (articlePaths.length === 0) { throw new Error("--articles needs at least one article path."); }
const articleKeys = []; for (const candidate of articlePaths) { const key = articleKeyOf(projectRoot, candidate); if (!key) { // Not fatal: `translate` may legitimately hand over a path outside blog/ (a page, say), // and refusing the whole batch over it would block the articles that are fine. if (!porcelain) { console.warn(`⚠ Not inside an article folder, ignored: ${candidate}`); } continue; } articleKeys.push(key); }
const { eligible } = eli5Candidates(projectRoot, locale, { articleKeys, assumeTranslated, }); const cost = eligible.length * ELI5_COST_PER_FILE;
if (porcelain) { // One line, two fields — the contract translation.sh reads. console.log(`${eligible.length}\t${cost.toFixed(4)}`); return; }
if (eligible.length === 0) { console.log(`✅ No ELI5 to generate for ${locale} — every snippet is up to date.`); return; }
if (dryRun) { console.log( `🔍 ${eligible.length} ELI5 sidecar(s) would be generated for "${locale}" ≈ $${cost.toFixed(2)}:`, ); eligible.forEach((f) => console.log(` ${path.relative(projectRoot, f)}`)); console.log("\nDry run — nothing written, no API call made."); return; }
// Announced once, for the whole run, before the first call — not per file. printCostNotice(backend, eligible.length);
let ok = 0; let failed = 0; for (const [index, source] of eligible.entries()) { const relative = path.relative(projectRoot, source); // A plain line, not a trailing `... ` write: generateEli5 logs lines of its own, which // would otherwise land mid-sentence. console.log(` [${index + 1}/${eligible.length}] ${relative}`); try { // force: the eligibility module already decided; a stale localized sidecar must be // overwritten, and generateEli5's own "file exists" guard would otherwise skip it. await generateEli5(source, { locale, force: true, backend, quoteCost: false }); ok++; } catch (err) { // Soft-fail, like the plugin's own ELI5 handling: a missing annotation degrades to the // English one, it never costs the reader the article. console.log(`❌ ${err.message}`); failed++; } }
console.log(`\n🧠 ELI5 ${locale}: ${ok} generated, ${failed} failed.`); if (failed > 0) { console.log( ` Those snippets keep showing their English annotation until regenerated.`, ); }}
// ── CLI ──────────────────────────────────────────────────────────────────────
// Guard: only run CLI logic when this file is the entry point, not when imported.const { fileURLToPath: _fileURLToPath } = await import("url");const _isMain = process.argv[1] === _fileURLToPath(import.meta.url);if (!_isMain) { /* exported as module — skip CLI */} else { const args = process.argv.slice(2);
if (args.length === 0 || args.includes("--help") || args.includes("-h")) { console.log(`Usage: node scripts/generate-eli5.mjs <source-file> [options] node scripts/generate-eli5.mjs --locale fr --articles <article-path>... [options]
Options: --force Regenerate even if the sidecar already exists --backend <name> Who writes the annotation: claude (default, paid, ~$0.01 per file) or ollama (local, free, no API key) — known: ${ELI5_BACKENDS.join(", ")} --locale <code> Write the explanations in that language, to <source-file>.eli5.<code>.json (known: ${Object.keys(LANGUAGES).join(", ")}) --articles Treat the positional arguments as ARTICLES, and generate every eligible snippet sidecar under them (requires --locale) --output <path> Write to a custom path instead of the default sidecar name --dry-run With --articles: report what would be generated, and its cost, without constructing the API client — spends nothing --porcelain With --articles: print "<count>\\t<cost>" only, for scripts --assume-translated With --articles: count the snippets of articles that are ABOUT to be translated, for quoting a price before the translation runs --help, -h Show this help
Examples: node scripts/generate-eli5.mjs blog/2026-01-01-my-post/Dockerfile node scripts/generate-eli5.mjs blog/2026-01-01-my-post/compose.yaml --force node scripts/generate-eli5.mjs src/my-file.sh --output docs/my-file.sh.eli5.json node scripts/generate-eli5.mjs --locale fr --articles blog/2026/09/17/docling --dry-run
Requires ANTHROPIC_API_KEY in your environment or in a .env file at the project root(except for --dry-run and --backend ollama, which never call the API).`); process.exit(0); }
const force = args.includes("--force"); const dryRun = args.includes("--dry-run");
let backend; try { backend = resolveBackend(args); } catch (err) { console.error(`Error: ${err.message}`); process.exit(1); }
const porcelain = args.includes("--porcelain"); const outputIdx = args.indexOf("--output"); const outputPath = outputIdx !== -1 ? args[outputIdx + 1] : null; const localeIdx = args.indexOf("--locale"); const locale = localeIdx !== -1 ? args[localeIdx + 1] : "en";
if (localeIdx !== -1 && !LANGUAGES[locale]) { console.error( `Error: unsupported --locale "${locale}" (known: ${Object.keys(LANGUAGES).join(", ")}).`, ); process.exit(1); }
// Values consumed by a preceding flag are not positional arguments. Miss one here and // `eli5 <file> --backend ollama` runs against a source file named "ollama". const valueIndexes = new Set( [outputIdx, localeIdx, args.indexOf("--backend")] .filter((i) => i !== -1) .map((i) => i + 1), ); const positionals = args.filter((a, i) => !a.startsWith("--") && !valueIndexes.has(i));
if (args.includes("--articles")) { if (locale === "en") { console.error("Error: --articles requires --locale (e.g. --locale fr)."); console.error(" The English sidecars are generated by the bulk script instead:"); console.error(` ${cmd("eli5:bulk")}`); process.exit(1); } runArticleBatch({ locale, articlePaths: positionals, dryRun, porcelain, assumeTranslated: args.includes("--assume-translated"), backend, }).catch((err) => { console.error("❌ Error:", err.message); process.exit(1); }); } else { const sourceFile = positionals[0];
if (!sourceFile) { console.error("Error: no source file specified."); console.error("Run with --help for usage."); process.exit(1); }
generateEli5(sourceFile, { force, outputPath, locale, backend }).catch((err) => { console.error("❌ Error:", err.message); process.exit(1); }); }} // end isMain guardThis script generates "Explain Like I'm Five" annotations for source code by sending files to an AI model (Claude or local Ollama) and storing the structured explanations as JSON sidecars. It supports both single-file generation and batch processing of article snippets in multiple languages, with cost estimation and validation of the AI's responses.
A few details worth noting:
- Language detection mirrors the
remark-snippet-loadermapping, so the two components always agree on what language a file is. - The prompt tells Claude to skip trivial lines and return only a JSON object. The
systemmessage instructs it to output pure JSON; the temperature is kept at a low value for consistent, factual explanations. - JSON cleaning validates that all keys are digit strings in range and all values are non-empty strings, so a malformed response from Claude cannot crash the build.
- Incremental generation: if the
.eli5.jsonalready exists, the script exits without calling the API. Use--forceto regenerate.
Usage
You can also add a convenience alias to package.json:
"scripts": {
  "eli5": "node scripts/generate-eli5.mjs",
  "eli5:bulk": "node scripts/bulk-eli5.mjs"
}
Then the call becomes yarn eli5 blog/2026-01-01-my-post/files/Dockerfile.
The output format
The script writes a file like this:
Only annotated lines appear. The consumer (the remark plugin and the React component) treats missing lines as having no badge.
Step 2 — The batch script
When you have many posts, running the generator file by file is tedious. scripts/bulk-eli5.mjs scans your entire blog/ directory, finds every <Snippet source="..."> reference, resolves the path, and generates the .eli5.json in one pass.
#!/usr/bin/env node/** * Batch "Explain Like I'm Five" generator. * * Scans all MDX/MD files under --dir (default: blog/) for <Snippet source="..."> usages, * resolves each source file, and generates a .eli5.json annotation file alongside it. * Already-existing .eli5.json files are skipped unless --force is passed. * * Usage: * node scripts/bulk-eli5.mjs [--force] [--dir blog/] [--dry-run] [--backend ollama] * * Requires ANTHROPIC_API_KEY in your environment or in a .env file at the project root — * unless --backend ollama is passed, which calls the local model instead and needs no key. */
import fs from "fs";import path from "path";import { fileURLToPath } from "url";import { createRequire } from "module";import { hashSource } from "./lib/eli5-hash.mjs";import { DEFAULT_BACKEND, ELI5_BACKENDS, callEli5Backend, modelFor, printCostNotice, resolveBackend,} from "./lib/eli5-backend.mjs";
const require = createRequire(import.meta.url);const __dirname = path.dirname(fileURLToPath(import.meta.url));const projectRoot = path.resolve(__dirname, "..");
// Load .env from project root (best-effort)try { const dotenv = require("dotenv"); dotenv.config({ path: path.join(projectRoot, ".env") });} catch { // rely on environment variables already set}
// --- Language detection (same as generate-eli5.mjs) ---const EXT_TO_LANG = { js: "javascript", mjs: "javascript", cjs: "javascript", jsx: "jsx", ts: "typescript", tsx: "typescript", py: "python", php: "php", sh: "bash", bash: "bash", zsh: "bash", css: "css", html: "html", json: "json", yml: "yaml", yaml: "yaml", md: "markdown", mdx: "markdown", dockerfile: "docker", ini: "ini", sql: "sql", xml: "xml", toml: "toml", env: "bash", txt: "plaintext", ps1: "powershell", bat: "batch", cmd: "batch",};
const BASE_NAME_TO_LANG = { dockerfile: "docker", ".env": "bash", ".gitignore": "plaintext", ".dockerignore": "plaintext", makefile: "makefile",};
function detectLang(filePath) { const baseName = path.basename(filePath).toLowerCase(); if (BASE_NAME_TO_LANG[baseName]) return BASE_NAME_TO_LANG[baseName]; const ext = path.extname(filePath).slice(1).toLowerCase(); return EXT_TO_LANG[ext] || ext || "plaintext";}
const SYSTEM_PROMPT = `You are a patient senior developer explaining code to a junior colleague.Given a source file with numbered lines, produce two things:
1. "summary": two to four plain-English sentences narrating what this snippet does as a whole and why, the way you'd explain it out loud to someone reading over your shoulder — not a recap of individual lines. No jargon unless immediately defined.2. "explanations": for each line a junior developer might find confusing, one or two plain-English sentences. Think "explain like I'm five but I'm also a developer". Skip blank lines, closing braces/brackets, import lines that are self-evident, comments that already explain themselves, trivially obvious assignments.
Return ONLY a valid JSON object shaped exactly like:{"summary": "...", "explanations": {"3": "...", "7": "..."}}Keys in "explanations" are line numbers as strings. Omit lines that need noexplanation. No markdown, no code fences.`;
async function generateForFile( absSource, { force = false, backend = DEFAULT_BACKEND } = {},) { const destPath = absSource + ".eli5.json";
if (!force && fs.existsSync(destPath)) { return { status: "skipped", path: destPath }; }
const code = fs.readFileSync(absSource, "utf-8"); const lang = detectLang(absSource); const lines = code.split("\n"); const numberedCode = lines.map((l, i) => `${i + 1}: ${l}`).join("\n");
const model = modelFor(backend); const raw = await callEli5Backend({ backend, systemPrompt: SYSTEM_PROMPT, userContent: `Language: ${lang}\n\n${numberedCode}`, maxTokens: lines.length > 50 ? 2048 : 1024, });
let parsed;
try { parsed = JSON.parse(raw); } catch { const match = raw.match(/\{[\s\S]*\}/); if (match) parsed = JSON.parse(match[0]); else throw new Error(`Invalid JSON from ${model} for ${path.basename(absSource)}`); }
const summary = typeof parsed.summary === "string" && parsed.summary.trim() ? parsed.summary.trim() : null;
// Validate const explanations = parsed.explanations && typeof parsed.explanations === "object" ? parsed.explanations : {}; const cleaned = {}; for (const [k, v] of Object.entries(explanations)) { if (/^\d+$/.test(k) && typeof v === "string" && v.trim()) { const idx = parseInt(k, 10) - 1; if (idx >= 0 && idx < lines.length) cleaned[k] = v.trim(); } }
const result = { version: 1, // The model that actually wrote this file — see scripts/lib/eli5-backend.mjs. model, generated: new Date().toISOString(), source: path.basename(absSource), sourceHash: hashSource(code), lang, summary, explanations: cleaned, };
fs.writeFileSync(destPath, JSON.stringify(result, null, 2) + "\n"); return { status: "generated", path: destPath, count: Object.keys(cleaned).length };}
// --- Find all MDX/MD files recursively ---function findMarkdownFiles(dir) { const results = []; for (const entry of fs.readdirSync(dir, { withFileTypes: true })) { const full = path.join(dir, entry.name); if (entry.isDirectory()) { results.push(...findMarkdownFiles(full)); } else if (entry.isFile() && /\.(mdx?|md)$/.test(entry.name)) { results.push(full); } } return results;}
// --- Extract source paths from <Snippet source="..."> usages ---const SNIPPET_SOURCE_RE = /<Snippet[^>]*\ssource="([^"]+)"/g;
function extractSourcePaths(mdxFile) { const content = fs.readFileSync(mdxFile, "utf-8"); const dir = path.dirname(mdxFile); const sources = []; let match; while ((match = SNIPPET_SOURCE_RE.exec(content)) !== null) { const srcAttr = match[1]; let absPath; if (srcAttr.startsWith("./") || srcAttr.startsWith("../")) { absPath = path.resolve(dir, srcAttr); } else { absPath = path.resolve(projectRoot, srcAttr); } sources.push(absPath); } return sources;}
// --- CLI ---const args = process.argv.slice(2);
if (args.includes("--help") || args.includes("-h")) { console.log(`Usage: node scripts/bulk-eli5.mjs [options]
Options: --force Regenerate even if .eli5.json already exists --backend <name> Who writes the annotations: claude (default, paid, ~$0.01 per file) or ollama (local, free, no API key) — known: ${ELI5_BACKENDS.join(", ")} --dir <path> Directory to scan (default: blog/) --dry-run Show what would be generated without calling the API --help, -h Show this help
Examples: node scripts/bulk-eli5.mjs node scripts/bulk-eli5.mjs --force node scripts/bulk-eli5.mjs --dir blog/2026 --dry-run node scripts/bulk-eli5.mjs --dir blog/2026 --backend ollama --force
Iterate locally, publish with Claude: --backend ollama is there to try a prompt change ona slice of the corpus without spending anything; the published sidecars stay Haiku-generated.
Requires ANTHROPIC_API_KEY in your environment or in a .env file at the project root(except for --dry-run and --backend ollama, which never call the API).`); process.exit(0);}
const force = args.includes("--force");const dryRun = args.includes("--dry-run");
let backend;try { backend = resolveBackend(args);} catch (err) { console.error(`Error: ${err.message}`); process.exit(1);}
const dirIdx = args.indexOf("--dir");const scanDir = dirIdx !== -1 ? path.resolve(projectRoot, args[dirIdx + 1]) : path.resolve(projectRoot, "blog");
if (!fs.existsSync(scanDir)) { console.error(`Error: directory not found: ${scanDir}`); process.exit(1);}
console.log(`🔍 Scanning ${path.relative(projectRoot, scanDir)} for Snippet usages...`);
const mdxFiles = findMarkdownFiles(scanDir);const sourceMap = new Map(); // absPath → Set of mdx files referencing it
for (const mdxFile of mdxFiles) { for (const src of extractSourcePaths(mdxFile)) { if (!sourceMap.has(src)) sourceMap.set(src, new Set()); sourceMap.get(src).add(path.relative(projectRoot, mdxFile)); }}
if (sourceMap.size === 0) { console.log('No <Snippet source="..."> usages found.'); process.exit(0);}
console.log( `Found ${sourceMap.size} unique source file(s) across ${mdxFiles.length} posts.\n`,);
if (dryRun) { for (const [src, refs] of sourceMap) { const relSrc = path.relative(projectRoot, src); const exists = fs.existsSync(src + ".eli5.json"); const action = exists && !force ? "SKIP" : "GENERATE"; console.log(` [${action}] ${relSrc}`); for (const ref of refs) console.log(` ← ${ref}`); } console.log("\nDry run — nothing written."); process.exit(0);}
// What this run will really call for: the sources that exist and are not being skipped.// Counting the map would quote a price for the ⏭ files too.const toGenerate = [...sourceMap.keys()].filter( (src) => fs.existsSync(src) && (force || !fs.existsSync(src + ".eli5.json")),).length;printCostNotice(backend, toGenerate);
let generated = 0, skipped = 0, errors = 0;
for (const [src] of sourceMap) { const relSrc = path.relative(projectRoot, src);
if (!fs.existsSync(src)) { console.warn(` ⚠ Source not found, skipping: ${relSrc}`); errors++; continue; }
process.stdout.write(` 📄 ${relSrc} ... `);
try { const result = await generateForFile(src, { force, backend }); if (result.status === "skipped") { console.log("⏭ skipped"); skipped++; } else { console.log(`✅ ${result.count} annotations`); generated++; } } catch (err) { console.log(`❌ ${err.message}`); errors++; }}
console.log(`\n──────────────────────────────────────`);console.log(`Generated: ${generated} Skipped: ${skipped} Errors: ${errors}`);
if (errors > 0) process.exit(1);This is a batch script that scans blog posts for code snippets, extracts the source files they reference, and generates AI-powered explanation files for each source. It uses either Claude or a local Ollama model to analyze the code and produce summaries plus line-by-line explanations for junior developers, writing the results as JSON sidecars alongside each source file.
Options reference
| Flag | Default | Description |
|---|---|---|
--dir <path> | blog/ | Directory to scan (relative to project root) |
--force | off | Regenerate even if .eli5.json already exists |
--dry-run | off | Show what would happen, no API calls |
How the bulk script works
Before diving into the migration workflow, it helps to understand exactly what the script does — and does not do.
How it finds files to annotate
The script reads every .md and .mdx file under --dir (default: blog/), and searches each one for occurrences of <Snippet source="..."> using a regular expression. For each match it resolves the source path to an absolute path, deduplicates (a file referenced in multiple posts is only processed once), then processes the list.
It does not annotate inline fenced code blocks — only <Snippet> calls that reference an external file via source="./files/...".
The skip rule — idempotent by design
For every source file, the script first checks whether <source-file>.eli5.json already exists:
- File exists →
⏭ skipped— zero API call, zero cost, instant. - File missing →
✅ N annotations— one API call to Claude, file written.
This means:
- You can run
yarn eli5:bulkas many times as you want. Only files that are missing their.eli5.jsonwill trigger an API call. - The first run is the only one that costs money (for existing articles). All subsequent runs are free.
- If you add a new article with a
<Snippet>next month, runningyarn eli5:bulkagain will annotate only that new file. - If the script is interrupted (network error, Ctrl+C), simply re-run it — already generated files are skipped, and only the remaining ones are processed.
Use --force only when you have intentionally edited a source file and want to regenerate its annotations from scratch.
Annotating your existing articles
If you have a blog with many articles — say 240 — you do not want to run the generator file by file. Here is the recommended migration workflow.
Phase 1 — Audit with dry-run
Before touching the API, get a clear picture of what you have. Run the bulk script with --dry-run on your entire blog:
This is instant — no API call is made. The output shows every source file referenced by a <Snippet source="..."> in any post, and tells you whether its .eli5.json already exists or still needs to be generated:
🔍 Scanning blog/ for Snippet usages...
Found 47 unique source file(s) across 240 posts.

  [SKIP]     blog/2025/03/12-wsl2-tricks/files/wsl.conf
             ← blog/2025/03/12-wsl2-tricks/index.md
  [GENERATE] blog/2025/04/05-docker-compose/files/compose.yaml
             ← blog/2025/04/05-docker-compose/index.md
  [GENERATE] blog/2025/04/05-docker-compose/files/Dockerfile
             ← blog/2025/04/05-docker-compose/index.md
  [GENERATE] blog/2025/06/20-zsh-config/files/.zshrc
             ← blog/2025/06/20-zsh-config/index.md
  ...

──────────────────────────────────────
Generated: 0  Skipped: 3  Errors: 0
Two things to notice here:
-
Only 47 source files for 240 posts. Most posts do not use
<Snippet source="...">at all — they use inline fenced code blocks. The bulk script ignores those automatically. You are not annotating 240 files; you are annotating only the posts that already use the Snippet component with an external source file. -
The
SKIP/GENERATElabels tell you at a glance which files already have an annotation and which still need one. This makes the dry-run useful after partial runs too.
Save the dry-run output if you want a permanent audit record:
Phase 2 — Estimate the cost
claude-haiku-4-5-20251001 is priced at a fraction of a cent per call. A typical source file (20–60 lines) costs roughly $0.0002 – $0.001. Multiply by the number of [GENERATE] entries in your dry-run output.
For 47 source files, you are looking at under $0.05 total. Even if every one of your 240 posts had a source file, the total cost would be under $0.25.
Phase 3 — Generate by scope
You can process the entire blog in one command, or scope it to a specific year or month. All paths are relative to the project root.
Process everything at once:
The script runs sequentially (one API call at a time), so there is no risk of hitting rate limits. On a typical connection, 47 files take about two minutes.
Process a single year:
Process a single month:
Process a single post folder:
This last form is equivalent to running generate-eli5.mjs individually for each source file in that post — but the bulk script handles deduplication automatically (if the same source file is referenced twice in the same post, it is only generated once).
Phase 4 — What the output looks like while running
🔍 Scanning blog/2025 for Snippet usages...
Found 31 unique source file(s) across 140 posts.

  📄 blog/2025/04/05-docker-compose/files/compose.yaml ... ✅ 6 annotations
  📄 blog/2025/04/05-docker-compose/files/Dockerfile ... ✅ 5 annotations
  📄 blog/2025/04/12-zsh-setup/files/.zshrc ... ✅ 9 annotations
  📄 blog/2025/05/01-devcontainer/files/devcontainer.json ... ✅ 7 annotations
  📄 blog/2025/06/20-fzf/files/fzf-preview.sh ... ⏭  skipped
  ...

──────────────────────────────────────
Generated: 30  Skipped: 1  Errors: 0
Each line tells you how many lines Claude decided to annotate. A file with 0 annotations would mean Claude found nothing non-trivial — this can happen for very short or very simple files. A file with ⏭ skipped already had a .eli5.json from a previous run.
The script is safe to interrupt and re-run. If it stops halfway (network error, API error, Ctrl+C), just run it again. Files that were already generated will show ⏭ skipped; only the remaining ones will be processed.
Phase 5 — Handle errors
If a file fails (Claude returns malformed JSON, network timeout), it shows:
📄 blog/2025/04/05-docker-compose/files/Makefile ... ❌ Invalid JSON from Claude
The script continues with the next file and exits with code 1 at the end (so a CI pipeline would catch it). To retry only the failed file:
If the same file keeps failing, add --force to regenerate with a fresh API call.
Phase 6 — Verify a sample
Before committing, open a post in yarn start and check that the ? badges appear on the right lines. Inspect one or two .eli5.json files to confirm the quality of explanations.
The ? badges are injected by the remark plugin at MDX compile time, not at runtime. This means yarn start (port 3000) and yarn build produce identical results for ELI5 annotations. You never need to run a full build just to preview tooltips.
If you generate a new .eli5.json while the dev server is already running, save the corresponding .md file to trigger MDX recompilation — the badges will appear on the next hot reload.
If an explanation is wrong or too verbose, edit the JSON file directly — it is just plain text, no regeneration needed.
Phase 7 — Commit
Commit the .eli5.json files alongside the source files they annotate. This is intentional: CI/CD does not need ANTHROPIC_API_KEY because the annotations are pre-generated and stored in git.
Summary — migration in five commands
Step 3 — Extend the remark plugin
Your remark-snippet-loader already reads the source file and injects code and lang props into the <Snippet> node at build time. If you have never written such a plugin, my search&replace plugin for Docusaurus article explains the remark plugin anatomy from scratch. Add eleven lines to also inject the ELI5 annotations when a .eli5.json exists alongside the source file.
In plugins/remark-snippet-loader/index.cjs, after the block that pushes the lang attribute:
The annotations are serialized as a JSON string (eli5json prop) so they fit into the MDX attribute model without needing to build an estree expression node. The Snippet component parses this string back into an object with JSON.parse.
This approach means the author does not need to change a single line of MDX. Add the .eli5.json file, rebuild — the tooltips appear automatically.
Step 4 — Update the Snippet component
The Snippet component needs two changes: a new Eli5CodeBlock subcomponent that renders code line by line with badges, and a small update to the main Snippet function to parse eli5json and route to the new renderer.
import React, { useState, useRef, useEffect, useCallback, useMemo, useId, type CSSProperties, type JSX, type ReactNode,} from "react";import { createPortal } from "react-dom";import Prism from "prismjs";import { useTokenize } from "prism-react-renderer";// Eli5CodeBlock (below) needs its own Prism grammars registered on this exact// `prismjs` singleton — everything beyond markup/html/xml/css/clike/javascript// (Prism's default bundle) only exists here as a side effect of requiring its// component file. `prism-react-renderer` (peer-depends on "prismjs": "*", so// it shares this same module instance) registers `additionalLanguages` the// same way whenever a native `<CodeBlock>` renders — meaning `Prism.languages// .bash` etc. was previously only defined here if some *other* CodeBlock had// already rendered first in this process/session. Registering every grammar// `Eli5CodeBlock` can receive (see remark-snippet-loader's `extensionToLang`// map) unconditionally, here, makes that no longer order-dependent.// markup/html/xml/css/javascript need no entry — already in Prism's default// bundle (verified empirically).import "prismjs/components/prism-jsx";import "prismjs/components/prism-typescript";import "prismjs/components/prism-python";import "prismjs/components/prism-markup-templating"; // prism-php's own dependencyimport "prismjs/components/prism-php";import "prismjs/components/prism-bash";import "prismjs/components/prism-json";import "prismjs/components/prism-yaml";import "prismjs/components/prism-markdown";import "prismjs/components/prism-docker";import "prismjs/components/prism-ini";import "prismjs/components/prism-sql";
import CodeBlock from "@theme/CodeBlock";import IconCopy from "@theme/Icon/Copy";import IconSuccess from "@theme/Icon/Success";import LogoIcon from "@site/src/components/Blog/LogoIcon";import clsx from "clsx";import { useVarResolver } from "@site/src/components/Vars/store";import { substitutePlainText, substituteChildren,} from "@site/src/components/Vars/substitute";import VarToken from "@site/src/components/Vars/VarToken";import styles from "./styles.module.css";import Translate, { translate } from "@docusaurus/Translate";
// Extract language from <code className="language-xyz"> inside childrenconst getLanguageFromChildren = (children: ReactNode): string | null => { const findLang = (node: ReactNode): string | null => { if (React.isValidElement(node)) { const props = node.props as { className?: unknown; children?: ReactNode; }; if (typeof props.className === "string") { const match = props.className.match(/language-(\w+)/); if (match) return match[1].toLowerCase(); } if (props.children) { const nested = props.children; if (Array.isArray(nested)) { for (const child of nested) { const lang = findLang(child); if (lang) return lang; } } else { return findLang(nested); } } } return null; }; return findLang(children);};
// Maps code language to styling variantconst mapLangToVariant: Record<string, string> = { apacheconf: "apacheconf", asm: "asm", bas: "vb", bash: "bash", bashrc: "bash", bat: "batch", batch: "batch", cjs: "js", cmd: "batch", css: "css", csv: "csv", diff: "diff", docker: "docker", gherkin: "gherkin", html: "html", ignore: "ignore", ini: "ini", java: "java", javascript: "js", js: "js", jsx: "js", json: "json", log: "log", makefile: "makefile", markdown: "md", markdownlint_ignore: "json", md: "md", mdx: "md", mjs: "js", none: "none", pascal: "pascal", php: "php", plaintext: "txt", powershell: "powershell", ps1: "powershell", py: "python", python: "python", qmd: "md", sh: "bash", sql: "sql", svg: "svg", toml: "toml", ts: "ts", tsx: "ts", txt: "txt", typescript: "ts", vb: "vb", vba: "vb", vbnet: "vbnet", vbs: "vb", xml: "xml", yaml: "yaml", yml: "yaml", zsh: "bash",};
// Map variant keys to their icon components and CSS classes// For retrieving the value for the iconify key, just go to "https://icon-sets.iconify.design/?query=python"// and, in the top right search area, type the name of the language.// When found, click on the desired icon and retrieve the "icon name" as displayed in the bottom part.interface VariantIcon { iconClassName: string; iconify: string; ariaLabel: string;}
const variantIcons: Record<string, VariantIcon> = { apacheconf: { iconClassName: styles.apacheconf_icon, iconify: "logos:apache", ariaLabel: "ApacheConf Logo", }, asm: { iconClassName: styles.asm_icon, iconify: "vscode-icons:file-type-assembly", ariaLabel: "Asm Logo", }, bash: { iconClassName: styles.bash_icon, iconify: "devicon:bash", ariaLabel: "Bash Logo", }, batch: { iconClassName: styles.batch_icon, iconify: "file-icons:ms-dos", ariaLabel: "Batch Logo", }, css: { iconClassName: styles.css_icon, iconify: "ph:file-css", ariaLabel: "CSS Logo", }, csv: { iconClassName: styles.csv_icon, iconify: "ph:file-csv", ariaLabel: "CSV Logo", }, diff: { iconClassName: styles.diff_icon, iconify: "ph:git-diff", ariaLabel: "Diff Logo", }, docker: { iconClassName: styles.docker_icon, iconify: "uil:docker", ariaLabel: "Docker Logo", }, docusaurus: { iconClassName: styles.docker_docusaurus, iconify: "logos:docusaurus", ariaLabel: "Docusaurus Logo", }, gherkin: { iconClassName: styles.gherkin_icon, iconify: "skill-icons:gherkin-light", ariaLabel: "Gherkin Logo", }, html: { iconClassName: styles.html_icon, iconify: "ph:file-html", ariaLabel: "HTML Logo", }, ignore: { iconClassName: styles.ignore_icon, iconify: "codicon:sync-ignored", ariaLabel: "Ignore Logo", }, ini: { iconClassName: styles.ini_icon, iconify: "ph:file-ini", ariaLabel: "INI Logo", }, java: { iconClassName: styles.java_icon, iconify: "vscode-icons:file-type-java", ariaLabel: "Java Logo", }, js: { iconClassName: styles.js_icon, iconify: "logos:javascript", ariaLabel: "JS Logo", }, json: { iconClassName: styles.json_icon, iconify: "ix:json-document", ariaLabel: "JSON Logo", }, log: { iconClassName: styles.log_icon, iconify: "ix:log", ariaLabel: "Log Logo", }, makefile: { iconClassName: styles.makefile_icon, iconify: "vscode-icons:file-type-makefile", ariaLabel: "GNU Makefile Logo", }, md: { iconClassName: styles.md_icon, iconify: "ph:markdown-logo", ariaLabel: "Markdown Logo", }, none: { iconClassName: styles.none_icon, iconify: "ph:empty", ariaLabel: "None Logo", }, pascal: { iconClassName: styles.pascal_icon, iconify: "file-icons:pascal", ariaLabel: "Pascal Logo", }, php: { iconClassName: styles.php_icon, iconify: "bi:filetype-php", ariaLabel: "PHP Logo", }, powershell: { iconClassName: styles.powershell_icon, iconify: "file-icons:powershell", ariaLabel: "Powershell Logo", }, python: { iconClassName: styles.python_icon, iconify: "devicon:python", ariaLabel: "Python Logo", }, sql: { iconClassName: styles.sql_icon, iconify: "ph:file-sql", ariaLabel: "SQL Logo", }, svg: { iconClassName: styles.svg_icon, iconify: "ph:file-svg", ariaLabel: "SVG Logo", }, toml: { iconClassName: styles.toml_icon, iconify: "tabler:toml", ariaLabel: "Toml Logo", }, ts: { iconClassName: styles.ts_icon, iconify: "logos:typescript-icon", ariaLabel: "TypeScript Logo", }, txt: { iconClassName: styles.txt, iconify: "ph:file-txt", ariaLabel: "Txt Logo", }, vb: { iconClassName: styles.vb_icon, iconify: "fluent:document-vb-16-regular", ariaLabel: "VB Logo", }, vbnet: { iconClassName: styles.vbnet_icon, iconify: "fluent:document-vb-16-regular", ariaLabel: "VbNet Logo", }, xml: { iconClassName: styles.xml_icon, iconify: "hugeicons:xml-01", ariaLabel: "XML Logo", }, yaml: { iconClassName: styles.yaml_icon, iconify: "devicon-plain:yaml", ariaLabel: "YAML Logo", },};
// ELI5 line-by-line renderer — used when eli5json prop is present.// Calls Prism.highlight() directly to get syntax-colored HTML per line,// then overlays interactive ? badges for annotated lines.// The tooltip is rendered via a React Portal into document.body so it// escapes every overflow:hidden / stacking-context ancestor.// C0 control characters other than tab/newline/carriage return, plus DEL. A few example files// carry them for real — `make.bat` colours its output with ESC sequences — and a raw control// character in the page is invalid HTML (the SSG minifier flags it on every build, in every// locale). They are shown as their Unicode "control picture" (ESC -> ␛) instead: visible, honest// about what the file contains, and valid markup.const isControlChar = (code: number): boolean => (code <= 0x1f && code !== 0x09 && code !== 0x0a && code !== 0x0d) || code === 0x7f;
function hasControlChars(text: string): boolean { for (let i = 0; i < text.length; i += 1) { if (isControlChar(text.charCodeAt(i))) return true; } return false;}
function showControlChars(text: string): string { if (!hasControlChars(text)) return text; let out = ""; for (let i = 0; i < text.length; i += 1) { const code = text.charCodeAt(i); // U+2400..U+241F picture each C0 control; U+2421 pictures DEL. out += isControlChar(code) ? String.fromCharCode(code === 0x7f ? 0x2421 : 0x2400 + code) : text[i]; } return out;}
interface Eli5CodeBlockProps { code: string; lang: string; eli5: Record<string, string>;}
// Eli5CodeBlock renders its own <pre>, bypassing Docusaurus's native// <CodeBlock> (see below) and losing its built-in copy button in the// process — reimplemented locally rather than pulling in// `@docusaurus/theme-common/internal`'s CodeBlockContext, which TODO 0112// already names as a suspect in an open React hydration bug.function useCopyToClipboard() { const [copied, setCopied] = useState(false); const timeoutRef = useRef<number | undefined>(undefined);
const copy = useCallback((text: string) => { navigator.clipboard.writeText(text).then(() => { window.clearTimeout(timeoutRef.current); setCopied(true); timeoutRef.current = window.setTimeout(() => setCopied(false), 1000); }); }, []);
useEffect(() => () => window.clearTimeout(timeoutRef.current), []);
return { copied, copy };}
function Eli5CodeBlock({ code, lang, eli5 }: Eli5CodeBlockProps): JSX.Element { const [activeLine, setActiveLine] = useState<string | null>(null); const [tooltipStyle, setTooltipStyle] = useState<CSSProperties | null>(null); const { copied, copy } = useCopyToClipboard(); // false until mounted client-side — gates the tooltip's document.body Portal, // which doesn't exist during SSR. const [mounted, setMounted] = useState(false); const badgeRefs = useRef<Record<string, HTMLButtonElement | null>>({});
useEffect(() => { // eslint-disable-next-line react-hooks/set-state-in-effect -- intentional mount flag, see comment on `mounted` above setMounted(true); }, []);
// `Prism.highlight()` + `.split("\n")` (the previous approach) corrupts any // token that spans multiple lines — a `/** … */` JSDoc comment most // commonly — because the highlighted HTML gets cut across an unclosed // `<span>`. Browsers silently repair that malformed HTML while parsing the // page, but repair it *differently* than what React's virtual tree expects // once it hydrates, which is a genuine structural mismatch (React error // #418) on any snippet whose language has multi-line comments/strings — // confirmed via a server-vs-hydrated-DOM diff on `docusaurus-cards.mdx` // (see TODO 0112). `useTokenize` avoids the string-splitting step entirely: // it walks Prism's real token tree and only ever hands back whole tokens, // already split at line boundaries. const grammar = useMemo( () => Prism.languages[lang] || Prism.languages.plaintext || Prism.languages.clike, [lang], ); const tokenizedLines = useTokenize({ prism: Prism, code, grammar, language: lang }); // A trailing `\n` in `code` makes normalizeTokens() append one synthetic // last "line" holding a single `{ content: "\n", empty: true }` token — // drop it so line numbers keep matching `eli5`'s 1-based keys, exactly like // the previous `rawLines.pop()` did for a trailing blank line. const lines = useMemo(() => { const last = tokenizedLines[tokenizedLines.length - 1]; if (last?.length === 1 && last[0].empty) { return tokenizedLines.slice(0, -1); } return tokenizedLines; }, [tokenizedLines]);
// Compute position: tooltip appears above the badge, right-aligned. const positionTooltip = useCallback((lineNum: string) => { const el = badgeRefs.current[lineNum]; if (!el) return; const rect = el.getBoundingClientRect(); setTooltipStyle({ top: rect.top, // translateY(-100%-gap) shifts it above right: window.innerWidth - rect.right, // right-align with the badge }); }, []);
const handleBadgeClick = useCallback( (lineNum: string) => setActiveLine((prev) => (prev === lineNum ? null : lineNum)), [], );
// Keep the tooltip glued to its badge: position is computed once on // hover/focus, but `position: fixed` doesn't move with scrolling — without // this, scrolling the page (or the horizontally-scrollable code block) // while a tooltip is open leaves it stranded at its old screen position. useEffect(() => { if (!activeLine) return undefined; const reposition = () => positionTooltip(activeLine); window.addEventListener("scroll", reposition, { capture: true, passive: true }); window.addEventListener("resize", reposition, { passive: true }); return () => { window.removeEventListener("scroll", reposition, { capture: true }); window.removeEventListener("resize", reposition); }; }, [activeLine, positionTooltip]);
const activeExplanation = activeLine ? eli5[activeLine] : null;
return ( <> <pre className={clsx(`language-${lang}`, styles.eli5_pre)}> <button type="button" className={styles.eli5_copy_button} onClick={() => copy(code)} aria-label={ copied ? translate({ id: "common.copied", message: "Copied" }) : translate({ id: "common.copyCode", message: "Copy code to clipboard" }) } title={translate({ id: "common.copy", message: "Copy" })} > {copied ? ( <IconSuccess className={styles.eli5_copy_icon} /> ) : ( <IconCopy className={styles.eli5_copy_icon} /> )} </button> <code className={`language-${lang}`}> {lines.map((lineTokens, i) => { const lineNum = String(i + 1); const explanation = eli5[lineNum]; const isActive = activeLine === lineNum;
return ( <div key={i} className={styles.eli5_line}> <span className={styles.eli5_code}> {lineTokens.map((token, tokenIdx) => ( <span key={tokenIdx} className={clsx("token", ...token.types)}> {/* Display only: the copy button still copies `code`, real bytes and all. */} {showControlChars(token.content)} </span> ))} </span> {explanation ? ( <span className={styles.eli5_badge_wrapper}> <button type="button" ref={(el) => { badgeRefs.current[lineNum] = el; }} className={clsx( styles.eli5_badge, isActive && styles.eli5_badge_active, )} aria-label={translate( { id: "snippet.explainLine", message: "Explain line {line}" }, { line: lineNum }, )} aria-expanded={isActive} onClick={() => handleBadgeClick(lineNum)} onMouseEnter={() => { positionTooltip(lineNum); setActiveLine(lineNum); }} onMouseLeave={() => setActiveLine(null)} onFocus={() => { positionTooltip(lineNum); setActiveLine(lineNum); }} onBlur={() => setActiveLine(null)} > ? </button> </span> ) : ( <span className={styles.eli5_badge_placeholder} /> )} </div> ); })} </code> </pre> {mounted && activeExplanation && tooltipStyle && createPortal( <span role="tooltip" className={styles.eli5_tooltip} style={tooltipStyle}> {activeExplanation} </span>, document.body, )} </> );}
// ELI5 verbose summary — a Show/Hide disclosure rendered below the code block,// giving a narrative explanation of the whole snippet (as opposed to// Eli5CodeBlock's per-line tooltips). Kept as its own component, deliberately// outside Eli5CodeBlock's render tree — see TODO 0112 (open React hydration// bug on Eli5CodeBlock/<CodeBlock>): this feature must not add surface area// there. Also kept as a sibling of the collapsible `snippet_content` div// (not nested inside it): nesting would let this block's own open/close// change the *inner* scrollHeight without the outer collapsible's height// (computed once per its own toggle) ever re-measuring, clipping the summary// whenever a reader opens it after the snippet was already expanded.interface Eli5SummaryBlockProps { summary: string;}
function Eli5SummaryBlock({ summary }: Eli5SummaryBlockProps): JSX.Element { const [open, setOpen] = useState(false); const contentRef = useRef<HTMLDivElement | null>(null); const [height, setHeight] = useState("0px"); const contentId = `eli5-summary-${useId()}`;
useEffect(() => { if (contentRef.current) { setHeight(open ? `${contentRef.current.scrollHeight}px` : "0px"); } }, [open, summary]);
return ( <div className={styles.eli5_summary_block}> <button type="button" className={styles.eli5_summary_toggle} onClick={() => setOpen((prev) => !prev)} aria-expanded={open} aria-controls={contentId} > <span> {open ? translate({ id: "snippet.hideExplanation", message: "Hide explanation" }) : translate({ id: "snippet.explain", message: "Explain this snippet" })} </span> <span className={styles.eli5_summary_toggle_right}> <span className={styles.eli5_summary_badge}> <Translate id="snippet.poweredByAi">Powered by AI</Translate> </span> <span className={`${styles.chevron} ${open ? styles.rotate : ""}`}> ▾ </span> </span> </button> <div ref={contentRef} id={contentId} className={styles.eli5_summary_content} style={{ maxHeight: height }} > <p className={styles.eli5_summary_text}>{summary}</p> </div> </div> );}
interface Props { filename?: string; title?: ReactNode; code?: string; children?: ReactNode; /** * Force the open/closed state. Leave undefined and the component decides: * open, unless the snippet is longer than COLLAPSE_OVER_LINES. * * Pass `false` explicitly on file-index sections (ProjectSetup articles, * "All Files at a Glance"): there the page is a LIST of files the reader * scans and opens one of, not a narrative the code belongs to. */ defaultOpen?: boolean; variant?: string; lang?: string; eli5json?: string; eli5summary?: string;}
/** * Above this many lines a snippet opens PARTIALLY: the first lines are shown * under a fade, with a "show the remaining N lines" control. Below it, the * snippet simply opens. * * 30 is roughly one screenful of code at 0.85rem/1.6 on a laptop — the point * where "I can take this in at a glance" stops being true. */const COLLAPSE_OVER_LINES = 30;
/** Height of the peek window, in lines. Deliberately less than * COLLAPSE_OVER_LINES so a truncated block always LOOKS truncated. */const PEEK_LINES = 18;
export default function Snippet({ filename, title, code, children, defaultOpen, variant, lang: pluginLang, eli5json, eli5summary,}: Props): JSX.Element { const contentRef = useRef<HTMLDivElement | null>(null);
// Parse eli5json string (injected by remark-snippet-loader) into an object const eli5 = useMemo((): Record<string, string> | null => { if (!eli5json || typeof eli5json !== "string") return null; try { return JSON.parse(eli5json); } catch { return null; } }, [eli5json]);
const eli5Summary = typeof eli5summary === "string" && eli5summary.trim() ? eli5summary.trim() : null;
const lineCount = useMemo( () => (typeof code === "string" ? code.replace(/\n$/, "").split("\n").length : 0), [code], );
const isLong = lineCount > COLLAPSE_OVER_LINES;
/* * The default is OPEN. A reader who clicked "Install Docker under WSL2" came * for the compose file; making them click again to see it is asking them to * work for the thing they searched for. * * Three concrete costs of the old closed-by-default, beyond the extra click: * - find-in-page broke. The collapsed content sits in a max-height: 0 / * overflow: hidden box, which Ctrl+F cannot reach: a reader searching the * page for a variable name got "no results" while the word was right * there. * - printing produced empty boxes. * - the ELI5 "Explain this snippet" control is gated on `open`, so the * line-by-line explanations nobody had expanded were never discovered. * * Long files do not get the old all-or-nothing treatment either: they open * truncated (see PEEK_LINES), so the reader sees WHAT it is immediately and * the page is not eaten by 300 lines. */ const [open, setOpen] = useState(defaultOpen ?? true); const [expandedLong, setExpandedLong] = useState(false);
const handleToggle = useCallback(() => setOpen((prev) => !prev), []); const handleExpandLong = useCallback(() => setExpandedLong(true), []); const contentId = `snippet-content-${useId()}`;
const lang = useMemo(() => { // 1. Check for the `lang` prop provided by your plugin if (pluginLang) return pluginLang;
// 2. Fallback to the existing logic for `children` const languageFromChildren = getLanguageFromChildren(children); if (languageFromChildren) return languageFromChildren;
// 3. Fallback to the filename extension if no other language is found if (typeof filename === "string") { const ext = filename.split(".").pop(); return mapLangToVariant[ext ?? ""] || "plaintext"; }
return "plaintext"; }, [pluginLang, children, filename]);
// Resolve `default` markers (TODO 0088) before rendering. `code` // (from `source=`/`code=`, including files loaded at build time) is plain // text feeding Prism, so substitution there is a string swap — no visible // "this is yours" underline, which the `children` path below gets for // free; an acceptable v1 trade-off, see Vars/readme.md. const resolve = useVarResolver(); const resolvedCode = useMemo( () => (code ? substitutePlainText(code, resolve) : code), [code, resolve], ); const resolvedChildren = useMemo( () => substituteChildren(children, resolve, (name, value, key) => ( <VarToken key={key}>{value}</VarToken> )), [children, resolve], );
// Use line-by-line ELI5 renderer when annotations are available and code is a string. // Otherwise fall back to Docusaurus CodeBlock (or raw children). // // Code holding control characters also takes the ELI5 renderer, with no annotations: it is the // only one that can show them escaped while its copy button keeps the original bytes. The // native <CodeBlock> would either print them raw or copy the escaped version. const codeBlock = useMemo(() => { const hasEli5 = Boolean(eli5 && Object.keys(eli5).length > 0); if (resolvedCode && (hasEli5 || hasControlChars(resolvedCode))) { return <Eli5CodeBlock code={resolvedCode} lang={lang} eli5={eli5 ?? {}} />; } if (resolvedCode) { return <CodeBlock className={`language-${lang}`}>{resolvedCode}</CodeBlock>; } return resolvedChildren; }, [resolvedCode, eli5, lang, resolvedChildren]);
const baseName = useMemo( () => typeof filename === "string" ? (filename.split("/").pop() ?? "").toLowerCase() : null, [filename], );
const isDockerFile = useMemo(() => { if (!baseName) return false; return ( baseName === "dockerfile" || baseName === "docker" || baseName.endsWith(".docker") || baseName.endsWith(".dockerfile") || baseName.endsWith(".dockerignore") || baseName.endsWith("compose.yaml") || baseName.endsWith("compose.yml") || baseName.endsWith("docker-compose.yaml") ); }, [baseName]);
const isDocusaurus = useMemo(() => baseName === "docusaurus.config.js", [baseName]);
const variantKey = useMemo( () => variant || (isDockerFile ? "docker" : isDocusaurus ? "docusaurus" : mapLangToVariant[lang]) || "none", [variant, isDockerFile, isDocusaurus, lang], );
const variantClass = styles[`variant_${variantKey}`] || ""; const IconInfo = variantIcons[variantKey] || variantIcons.none; const { iconify, ariaLabel } = IconInfo;
const displayTitle = title || filename || (lang ? lang.toUpperCase() : translate({ id: "snippet.defaultTitle", message: "Snippet" }));
// Peek mode: long, open, and the reader has not asked for the rest yet. const peeking = open && isLong && !expandedLong;
return ( <div className={clsx(styles.snippet_block, variantClass)}> <button type="button" className={styles.snippet_summary} onClick={handleToggle} aria-expanded={open} aria-controls={contentId} > <span className={styles.filename_wrapper}> <LogoIcon name={iconify} className={styles.snippet_logo} aria-label={ariaLabel} size="32" /> {displayTitle} </span> <span className={clsx(styles.chevron, open && styles.rotate)}>▾</span> </button>
{/* Conditional render, not a max-height animation on a permanently mounted div. With the old approach the collapsed code stayed in the DOM inside an overflow: hidden box — invisible to Ctrl+F but still found by a screen reader, which is the worst of both. Unmounting is honest: closed means closed. */} {open && ( <div ref={contentRef} id={contentId} className={clsx(styles.snippet_content, peeking && styles.snippet_peek)} style={peeking ? { ["--peek-lines" as string]: String(PEEK_LINES) } : undefined} > <div className={styles.snippet_inner}>{codeBlock}</div> {peeking && ( <button type="button" className={styles.snippet_expand} onClick={handleExpandLong} > <Translate id="snippet.showRemaining" values={{ count: lineCount - PEEK_LINES }} description="Control revealing the rest of a truncated snippet" > {"Show the remaining {count} lines"} </Translate> </button> )} </div> )}
{open && eli5Summary && <Eli5SummaryBlock summary={eli5Summary} />} </div> );}This is a React component that displays code snippets with optional explanations and interactive features. It handles syntax highlighting using Prism, supports line-by-line annotations with tooltips, shows verbose summaries powered by AI, and truncates long code blocks to avoid overwhelming the reader while keeping the full content available to search and screen readers.
How the renderer works
When eli5json is present and code is a string, the component calls Prism.highlight() directly instead of delegating to Docusaurus's <CodeBlock>. Prism is already bundled by Docusaurus — importing it is safe and has no bundle-size cost.
The highlighted HTML is split by newline. Each line becomes a <div> containing:
- A
<span>with the syntax-highlighted code (viadangerouslySetInnerHTML— safe because Prism only wraps tokens in<span>elements) - Either a
?button (if the line has an explanation) or an invisible placeholder of the same width (to keep all lines aligned)
The tooltip appears on hover via a onMouseEnter/onMouseLeave pair on the badge wrapper, and toggles on click for keyboard/mobile access. Focus/blur handlers make it keyboard-accessible without extra ARIA trickery.
When eli5json is absent (the normal case), the component behaves exactly as before — <CodeBlock> is used, nothing changes.
Step 5 — Add the CSS
Add these classes to src/components/Snippet/styles.module.css:
The eli5_badge_placeholder is worth explaining: every line in the code block must have a right-side element of the same width, whether it has a badge or not. Without the placeholder, lines without a ? would be narrower and the code would appear ragged.
Author workflow (end to end)
For each blog post that contains <Snippet> blocks, the workflow after publishing once is:
If the source file changes after publication, regenerate with --force:
Environment setup
Step 1 — Create an Anthropic account and get an API key
If you already have a Claude Pro subscription (claude.ai), that covers the chat interface only — it does not include API access. The generation scripts use the Anthropic API, which is a separate, pay-as-you-go product billed by token usage. You need a distinct account on console.anthropic.com with a credit balance. The good news: annotating 240 articles with claude-haiku-4-5 costs a few cents in total (Haiku is the least expensive Claude model, at $1 per million input tokens, and each source file is only a few hundred tokens).
Go to https://console.anthropic.com and sign up (or log in if you already have an account). Once logged in:
- Click Settings in the left sidebar (or navigate directly to
https://console.anthropic.com/settings/keys). - Select API Keys from the settings menu.
- Click Create Key.
- Give your key a name (e.g.
docusaurus-eli5) so you can identify it later. - Copy the key immediately — it is shown only once and cannot be retrieved after you close the dialog. It looks like
sk-ant-api03-....
Store the key somewhere safe (a password manager works well). If you lose it, you will need to create a new one.
Do not paste your key into source code, commit it to git, or share it publicly. A leaked key can be used to make API calls billed to your account.
You will also need a billing credit balance to make API calls. In the Anthropic console, go to Settings → Billing and add a small credit (a few US dollars is more than enough to annotate hundreds of blog posts with Haiku — the cost is fractions of a cent per file).
Step 2 — Add the key to your project
Create a .env file at the root of your Docusaurus project (next to package.json):
# .env — do not commit this file
ANTHROPIC_API_KEY=sk-ant-api03-...
Then make sure .env is in your .gitignore:
The key is read by the generation scripts at authoring time only. It is never included in the built site or needed in CI — the .eli5.json annotation files are committed to git alongside the source files.
Step 3 — Install dependencies
dotenv and @anthropic-ai/sdk are already present as dependencies in this project. If you are starting a fresh Docusaurus project, install them as dev dependencies:
Known limitations
- Requires the
sourceprop — the ELI5 renderer activates only when the remark plugin injectscodeas a string (i.e., when you usesource="./files/myfile"). Snippets that use inlinechildren(fenced code blocks inside the MDX) are not annotated. - Stale annotations — if you edit a source file significantly after generating
.eli5.json, the annotations may no longer match the lines. Run--forceto refresh. There is no automatic staleness detection. - Long lines — if a line wraps visually (overflow-x scrolls), the
?badge stays at the end of the logical line, which may be off-screen. This is an edge case for most file types (Dockerfile, YAML, bash) where lines are short. - Prism language coverage —
Prism.highlight()falls back to plain text for languages not registered in Docusaurus's Prism bundle. The most common file types (Dockerfile, YAML, Bash, JSON, JavaScript) are all in the default bundle.
What Claude model to use
The scripts use claude-haiku-4-5-20251001, which is the fastest and least expensive Claude model. For a 20-line Dockerfile, one call costs a fraction of a cent and returns in under two seconds. The quality is sufficient for the ELI5 use case — short, factual explanations of well-known constructs.
If you want more nuanced explanations (for example, for complex shell pipelines or advanced YAML anchors), switch to claude-sonnet-4-6 in the scripts. The prompt and output format remain identical.
Extending the idea
A few directions worth exploring once the base feature is working:
- Difficulty levels — the prompt could ask Claude to tag each explanation as
beginner/intermediate/advancedand the badge could change color accordingly (?in green/yellow/red). - Localization — pass a
langprop to the script and addPlease respond in Frenchto the system prompt. The.eli5.jsonformat already has alangfield for this. - Staleness detection — add a
sourceHashfield (SHA-256 of the source file at generation time) to.eli5.json. The remark plugin can compare it to the current file hash and emit a warning during build when they diverge. - Automatic regeneration hook — a
yarn buildpre-hook ("prebuild": "node scripts/bulk-eli5.mjs") would regenerate all missing annotations before each build. Combined withANTHROPIC_API_KEYin CI secrets, this makes annotation generation fully automatic.
This article is part of the Creating Docusaurus components series:
- Change how Docusaurus will create img tags
- Overrides the generation of img tags with Docusaurus
- Organize Your Docusaurus Content with a Custom Series Component
- Providing a go to the top button in Docusaurus posts
- Creating a search&replace plugin for Docusaurus
- A component for showing code snippets in a Docusaurus blog
- A Docusaurus component that alerts readers the article is over a year old
- Showing the changelog of your post
- Inject ASCII Art in any HTML pages rendered by Docusaurus
- Best Practice - Customizing the Docusaurus RSS Feed for Full Content & Images
- Running some checks on your Docusaurus images
- Tags management in Docusaurus
- Automating TL;DR Summaries with Gemini AI
- Introducing the ProjectSetup Component - A Standardized Way to Share Project Structures
- How to indicate AI-assisted content in a Docusaurus blog
- Bring Your CLI Tutorials to Life with a Typewriter Terminal
- Meerkat Mischief: Sprinkling Easter Eggs Across my Blog
- AI-Powered Code Tooltips in Docusaurus — Explain Like I'm Five
- Adding Reader Reactions to Your Docusaurus Blog
- Your Blog Is Unreadable to an AI. Here Is the Fix.
- Shake Your Phone, Startle the Meerkat
- Add a "Copy as Markdown" Button to Your Docusaurus Blog
- Ask My Blog: Turning 259 Articles Into 2,160 Searchable Questions
- The Third Door: A Floating Chat Bubble, and the Feature Nobody Could Find
- Drawing a Map of My Own Blog
- Let Readers Flag Issues — A Multi-Type Feedback Widget for Docusaurus
Loading comments…
Related posts
Drawing a Map of My Own Blog
October 8, 2026
Ask My Blog: Turning 259 Articles Into 2,160 Searchable Questions
September 28, 2026
Add a "Copy as Markdown" Button to Your Docusaurus Blog
September 10, 2026
Shake Your Phone, Startle the Meerkat
August 27, 2026